Voice: STT, TTS and VAD
STT, TTS, and VAD settings are stored in the flow and applied to calls. Providers are selected from the configured provider directories. Provider keys are stored in the environment configuration, while self-hosted endpoints do not require a provider key. Most of these settings are in the Voice card of the Settings tab:- Speech-to-text · ASR model — the recognition model; its parameters are behind the STT parameters gear.
- Text-to-speech · Voice — the agent’s voice; the voice, its model and its settings are chosen in the voice window, while the output format and the emergency fallback are behind the TTS parameters gear.
- Turn-taking — interruptions, Active listening, Background audio and Phrase fixups; the speech detector is behind the Turn-taking parameters gear.
- Audio input · advanced — a collapsible block under the card.
STT
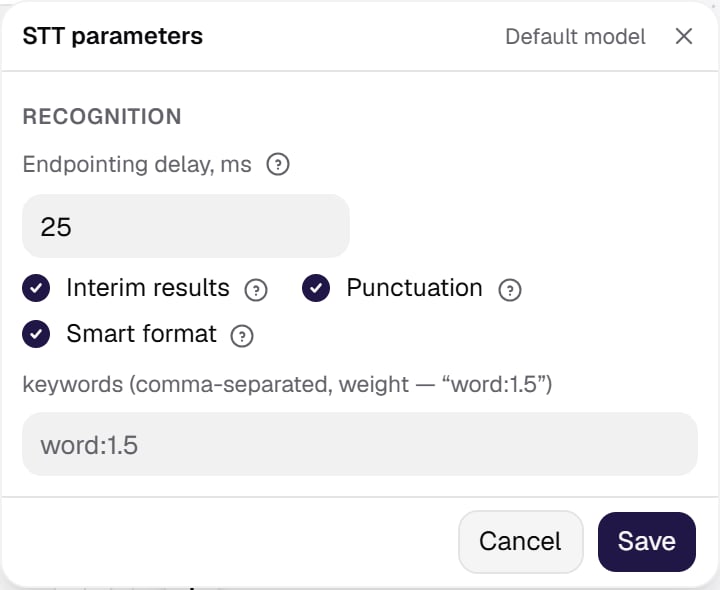
STT (speech-to-text) converts the caller’s voice into text for the agent. The recognition model is picked in Speech-to-text · ASR model by reference to an entry of the ASR model directory, with its provider shown beside it. A model marked deprecated is labelled as such right in the field. Recognition has no language of its own: it listens to all agent languages. The STT parameters gear shows the chosen model in its header and holds:- For Deepgram models also Endpointing delay, ms, the Interim results, Punctuation and Smart format checkboxes. Interim results means the transcript arrives as the caller speaks rather than in one piece at the end. Batch models have no interim results: the utterance is recognized whole once the caller stops.
- keywords (comma-separated, weight — “word:1.5”) — recognition hints, words the recognizer should hear more accurately: names, terms, abbreviations. The field is available for Deepgram, Cybernet, Soniox, Azure, AssemblyAI and Gladia models; a weight after a colon is understood by Deepgram. How to write hints for Cybernet models, with examples, is in the Voice lesson.
- ASR model parameters — the provider-specific parameters of the selected directory entry, read-only.
- Override provider-specific parameters (JSON) — this agent’s own values on top of the entry’s parameters; see below.
Overriding the model’s parameters for one agent
A directory entry carries the same provider parameters for every agent that uses it. When one agent needs a different value for one of them, you no longer have to create a separate directory entry for it: put the difference into Override provider-specific parameters (JSON).- The override is laid over the entry key by key. A top-level key in the override replaces the entry’s value for that key; every other key of the entry stays as it is. Write only the keys you want to change.
keep_tagsandnormalize_numberstake onlytrueorfalse. Anything else is refused with “keep_tags and normalize_numbers take only true or false”.- The override belongs to the selected entry. Picking a different ASR model clears it, and so does switching away from the directory; picking the same entry again keeps it. A bulk replacement of the directory entry across agents keeps the override.
- It is frozen on publish together with the rest of the agent: a published version keeps the combined parameters it was published with.
TTS
TTS (text-to-speech) converts the agent’s text responses into audio. The agent’s voice is set in the Text-to-speech · Voice group: the value button opens the voice window. In that window you choose the voice, its model, the agent’s speaking speed and the fine-tuning of the sound. The TTS parameters gear holds what belongs to the agent rather than to the voice: the output format and the emergency fallback. Synthesis has no language of its own: the voice speaks the current language of the call.The voice window
The Choose a voice window has two columns; its header names the agent and its languages.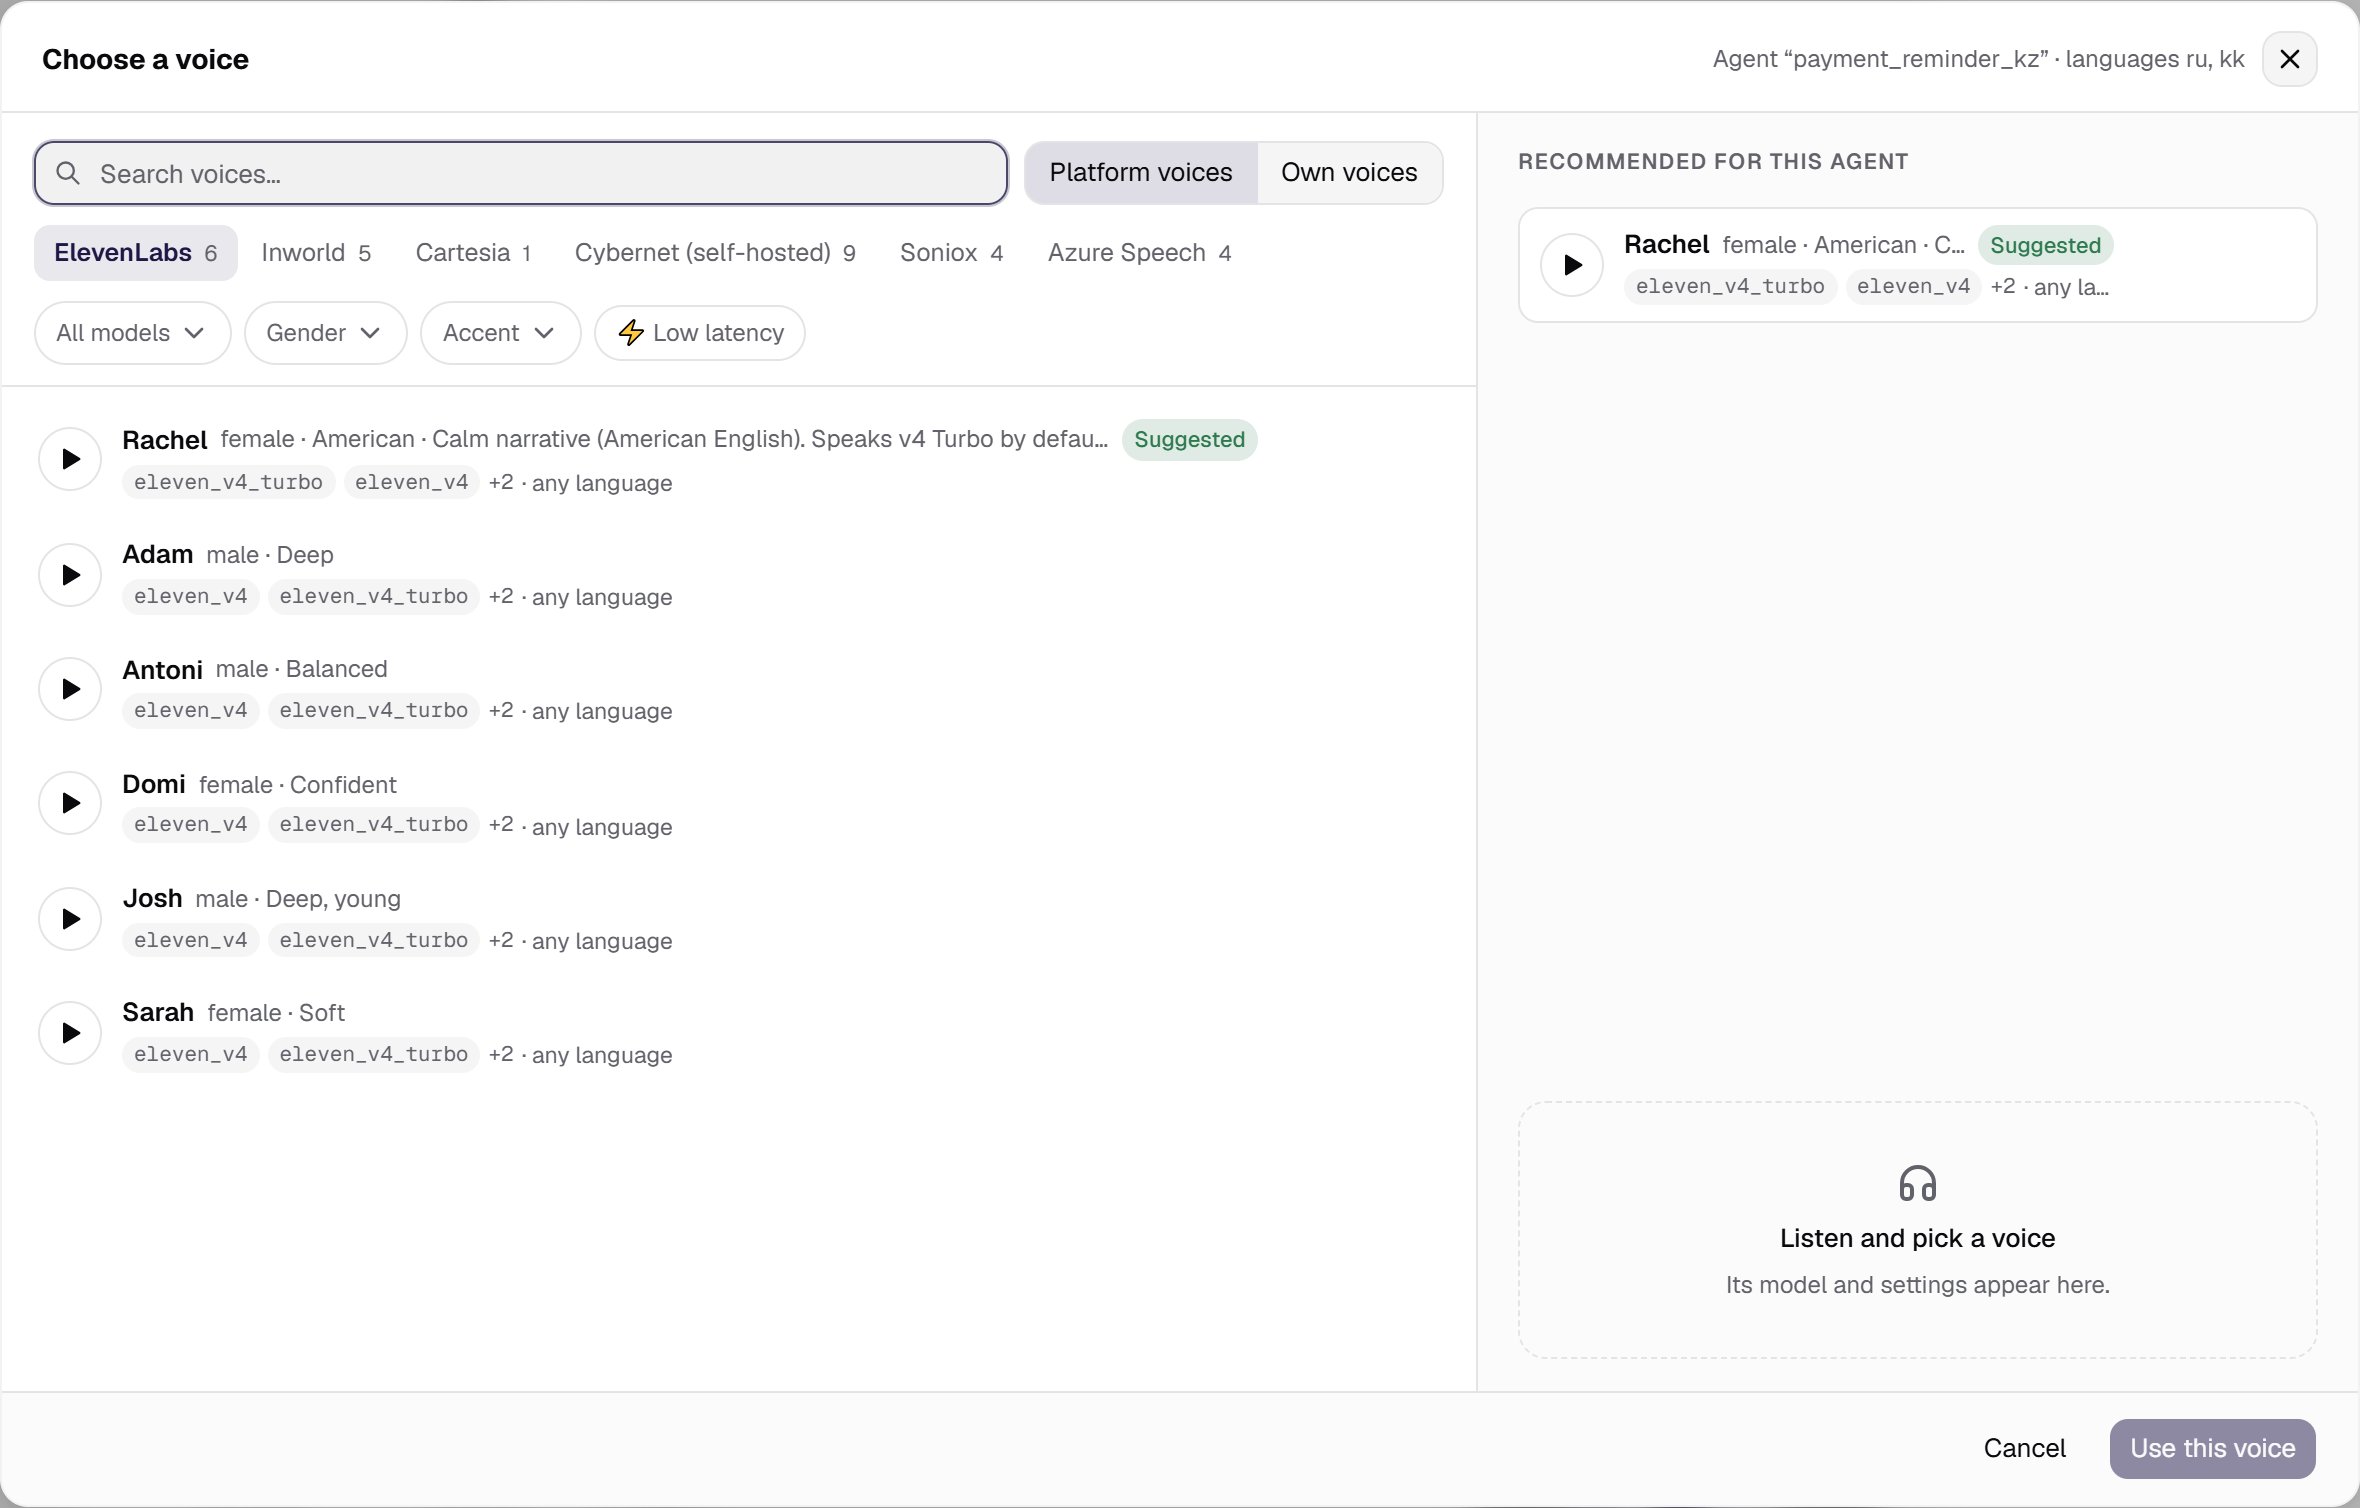
- Search voices… — by name, voice ID, model, provider and description.
- Platform voices / Own voices — the source of the voices. The switch appears when the directory has voices of both kinds.
- Provider tabs — ElevenLabs, Cartesia, Inworld and others, each with its voice count. The window opens on the provider of the current voice.
- Filters: Model — voices that can speak on the chosen model; Gender; Accent — when the voices of the tab have one; ⚡ Low latency. When a value is chosen in Gender or Accent, voices without that mark are hidden.
- A voice row — the ▶ listen button, the name, gender, accent and description, the Suggested, deprecated and custom marks, the models the voice can speak on and the number of languages. Suggested voices are at the top of the list, deprecated ones at the bottom.
- Until a voice is selected, the panel shows Recommended for this agent — the suggested voices of the current tab, with the filters applied.
- A click on a row selects the voice. The panel shows its name with a large listen button, the provider, gender, accent, languages and the No streaming and No word timing marks when they apply. The list shows only the voices that support every agent language on at least one of their models. The current voice, if it stopped fitting, stays first in the list marked Does not support: ….
- Model — model cards, when the voice allows several. The voice’s own model is marked entry model.
- Speed — the agent’s speaking speed; an empty field means the provider’s default. For a cybernet voice at 0.9 and below the cabinet warns that the voice quality degrades. Each provider has its own accepted range — see Voice settings outside the provider’s range.
- Fine-tune — a collapsible block: for an ElevenLabs voice, its sound settings; for a voice with a parameter passport, the passport fields; see Overriding the voice’s parameters for one agent.
- Developer — a collapsible block: Parameters outside the passport (JSON), the “provider · voice ID · model” line and Catalog voice parameters — the voice’s own parameters, read-only.
Listening to a voice
The ▶ button plays a sample — a short greeting in the agent’s primary language; a hint in the panel names the sample language. If the voice does not support that language, the greeting plays in one of the voice’s languages, or in English when none fits. The sample uses the model chosen in the model card or in the Model filter, and otherwise the voice’s own model. Speed and fine-tuning do not affect the sample: it plays the voice with its directory parameters. One sample plays at a time; pressing the button again pauses it. Soniox and Azure voices have no sample: the button is inactive, and its hover hint explains that the provider has no synthesizer outside a call. If a sample fails to load, a line with the reason appears under the list.What picking another voice resets
The model, the ElevenLabs settings, the passport fields and the parameters under Developer belong to the voice. When you select another voice in the window, the panel starts over: the voice’s own model, the ElevenLabs defaults from the table below, no own parameters. The agent’s speed is kept. Go back to the current voice, and the panel shows everything that was set for it again.A voice outside the directory
A voice is picked from the directory only; there is no manual entry. If the agent holds a voice without a directory reference, the group’s button shows Outside the directory with the provider and the voice ID. Such a voice is spoken on calls but is read-only in the cabinet: to set it up, pick a voice from the directory.The TTS parameters gear
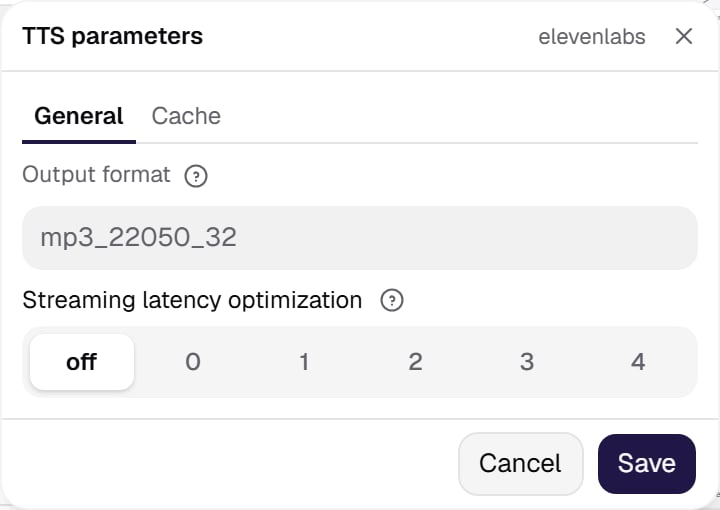
The gear shows the voice and provider in its header. A tab that holds a value off its default carries a dot. General- Output format — empty means the plugin default.
- Streaming latency optimization — for an ElevenLabs voice: off or 0–4.
Overriding the voice’s parameters for one agent
It works the same way as for the ASR model above. The values are set in the voice window:- Passport fields — under Fine-tune, when the voice has a parameter passport. Each parameter the passport declares for the chosen model gets its own field: a slider, a select, a number, a text field or a switch. Next to the field you see where the value comes from: own value, value of the entry or vendor default; a parameter marked set by the entry cannot be changed. A value of the wrong type, outside the range or not one of the allowed variants is highlighted and not saved.
sample_rateof a cybernet voice — the synthesis sample rate: 8000, 16000, 22050 or 24000 Hz, 8000 by default. On a phone call a rate above 8000 adds no quality — the line carries 8 kHz anyway; 24000 is for web calls and the widget.- Parameters outside the passport (JSON) — under Developer: the keys the passport does not know, and for a voice without a passport, every key you want to change, for example
{"apply_text_normalization": "on"}. A passport key typed here is refused — it is set in its own field under Fine-tune. A cybernet voice has a strict passport and no such field.
- They are laid over the directory voice key by key. A top-level key replaces the voice’s value; every other key stays as it is.
- They survive saving and publishing.
- They belong to the selected voice. Picking a different voice clears them, together with the chosen Model.
- They apply to the agent’s own voice only. A node voice has its own values — see Node model and voice parameters; the fallback voice does not get them.
- They are part of the TTS cache key: editing them changes which cached phrases are used.
- A parameter rejected by the passport — wrong type, outside the range, not one of the allowed variants, set by the entry or not available for the chosen model — blocks publishing. Fix the value in the voice window, under Fine-tune or Developer.
- A parameter that is not in the passport is a warning: it is sent to the provider unchecked.
- A model that is not in the voice’s model list is a warning: the entry’s own model is published instead.
Voice settings outside the provider’s range
On ElevenLabs,speed accepts only 0.7–1.2, and stability, similarity_boost and style accept 0.0–1.0:
- A value outside the range is brought to the nearest limit. For example,
speed1.4 is spoken as 1.2. - A value that is not a number is not sent, and the provider uses its default.
use_speaker_boosttakes yes/no. - The check before publishing and before a campaign launch warns about both cases: “…will speak with speed 1.2 instead of 1.4” or “…the setting will not be sent”. These are warnings: the agent can still be published and the campaign launched.
speed, stability, similarity_boost, style and use_speaker_boost can also be written into Parameters outside the passport (JSON); there they take priority over the Speed field and the Fine-tune fields.
ElevenLabs voice settings
An ElevenLabs voice has fields in the voice window that shape how it sounds: speed is in the voice panel, the rest are under Fine-tune.
Emotion is controlled by
stability and style. The main lever is stability: to make the agent sound livelier, start with 0.35–0.4 and style at 0. If that is not enough, add style at 0.1–0.2 — above that, the latency usually becomes noticeable on a live call. On fast models, including the default eleven_flash_v2_5, style may have little effect on the sound.
VAD & interruptions
VAD (voice activity detection) controls when speech starts and ends, while interruption settings control whether the caller can cut the agent off. The settings are read at call start; nothing needs rebuilding. The Turn-taking group of the Voice card:- Allow interruptions — whether the caller can interrupt the agent. Two fields always stand under it:
- Min duration, sec (
min_interruption_duration) — how much speech it takes to interrupt. An empty field means auto: the value is chosen at call start from the agent’s ASR; the field shows it as a hint. - Min words (
min_interruption_words) — how many recognized words the caller must say before the agent stops talking; 0 means no word gate. An empty field means auto, by the same rule.
- Min duration, sec (
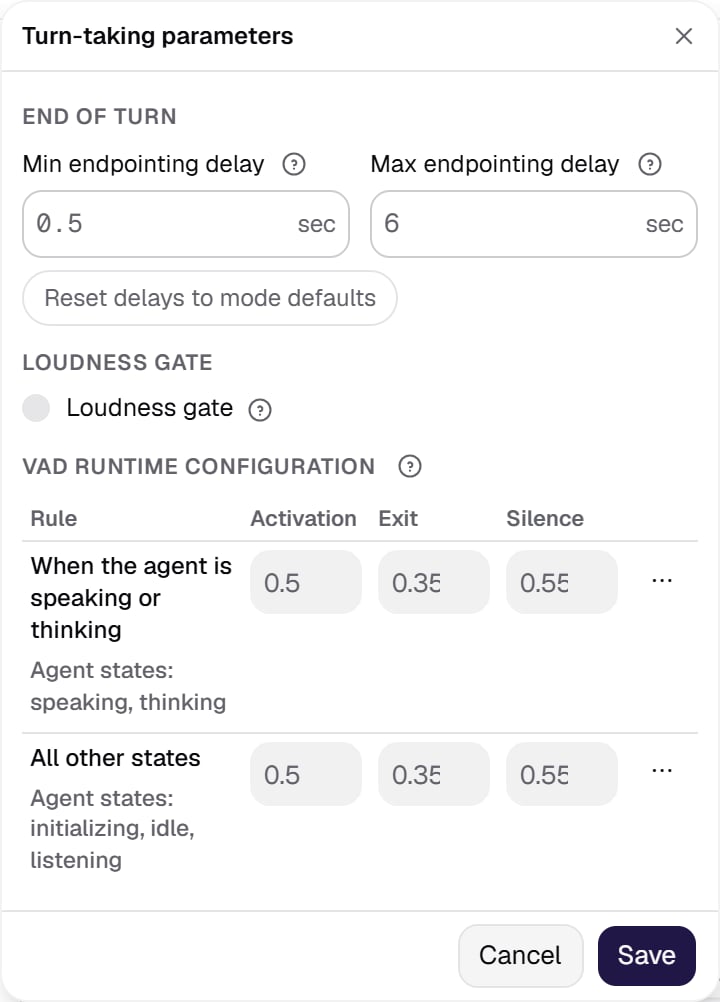
- End of turn — Min endpointing delay and Max endpointing delay, sec: the shortest wait after the caller stops before the turn is closed and the longest wait before it is closed anyway. An empty field takes the defaults of the turn detection mode; the field shows them as a hint. Reset delays to mode defaults clears both.
- Loudness gate — a second check on speech: a quiet frame does not start an utterance even when the model calls it speech. Helps on noisy lines.
- VAD runtime configuration — the speech detector thresholds per agent state; see below.
- Prefix padding, sec (
prefix_padding_duration) — how much audio is kept ahead of the detected speech. - Max buffered, sec (
max_buffered_speech) — the longest single utterance the agent keeps in memory. - Sample rate (
sample_rate) — 8000 for narrowband telephony, otherwise 16000.
Auto: the defaults your recognizer gets
A streaming model returns text as the caller speaks; a batch model returns the whole utterance once they have finished (see Interim results in the STT section). One set of interruption thresholds cannot fit both: on a batch model the words can only be counted after the caller pauses, so a word gate postpones the interruption to the end of the phrase. Leaving a field empty means auto — the platform fills in the set that matches the model you picked under STT:
A number you type always beats auto: the platform leaves your value alone. The duration threshold on every branch has no field of its own — it comes with the set.
Per-state thresholds and the loudness gate
VAD runtime configuration in the Turn-taking parameters gear is a table of rules — the same thresholds, but per agent state. It has two rows: When the agent is speaking or thinking and All other states. The columns are Activation (activation_threshold), Exit (deactivation_threshold) and Silence (min_silence_duration). The ⋯ button at the end of a row opens More fields: min_speech_duration and — while the loudness gate is on — the three loudness fields activation_volume, deactivation_volume and release_hold; the platform does not apply them without the gate. An empty field shows, as a hint, the value that applies: in the first row — the value of All other states, in the second — the platform default. The set of rules itself is fixed in code, only the numbers change. If a combination of values is wrong, a warning appears under the row.
Agent states. During a call the agent is always in one of five states — their names are shown under the rule name:
The thresholds switch as soon as the state changes. The two rules exist so the speech detector can be stricter while the agent is speaking or preparing a reply: at that time the line picks up the echo of the agent’s voice, noise and short “uh-huh”s, which should not count as the caller’s turn and cut the agent off. While the agent is listening, the detector stays sensitive so it does not miss a quiet answer.
What the thresholds mean (the same in both rules):
activation_threshold— the detector’s confidence that the sound is speech, from 0 to 1, at which it counts the start of speech. 0.5 by default. The higher it is, the more certain the speech must sound: noise and echo are taken for the caller less often, but a quiet or clipped answer may not count either.deactivation_threshold— the confidence below which speech counts as over. It must be lower than the start threshold, so speech does not break up in the pauses between words. An empty field means the start threshold minus 0.15, that is 0.35 with a start threshold of 0.5.min_speech_duration, sec (More fields) — how long the sound must stay above the threshold for the detector to count the start of speech. 0.05 by default. Higher means short clicks and “uh-huh”s do not count, but the start of an answer is registered a little later.min_silence_duration, sec (the Silence column) — how much silence counts as the end of a turn. 0.55 by default.
activation_volume (0.01) immediately, but it does not close at deactivation_volume (0.005) right away: release_hold, sec (0.3) is how long the level has to stay low before the gate closes. The hold exists for the quiet caller: their voice dips at the tail of every syllable, and without a pause before closing the gate would cut their speech syllable by syllable. Set it to 0 if you want the gate to close on the first quiet frame.
Turn detection
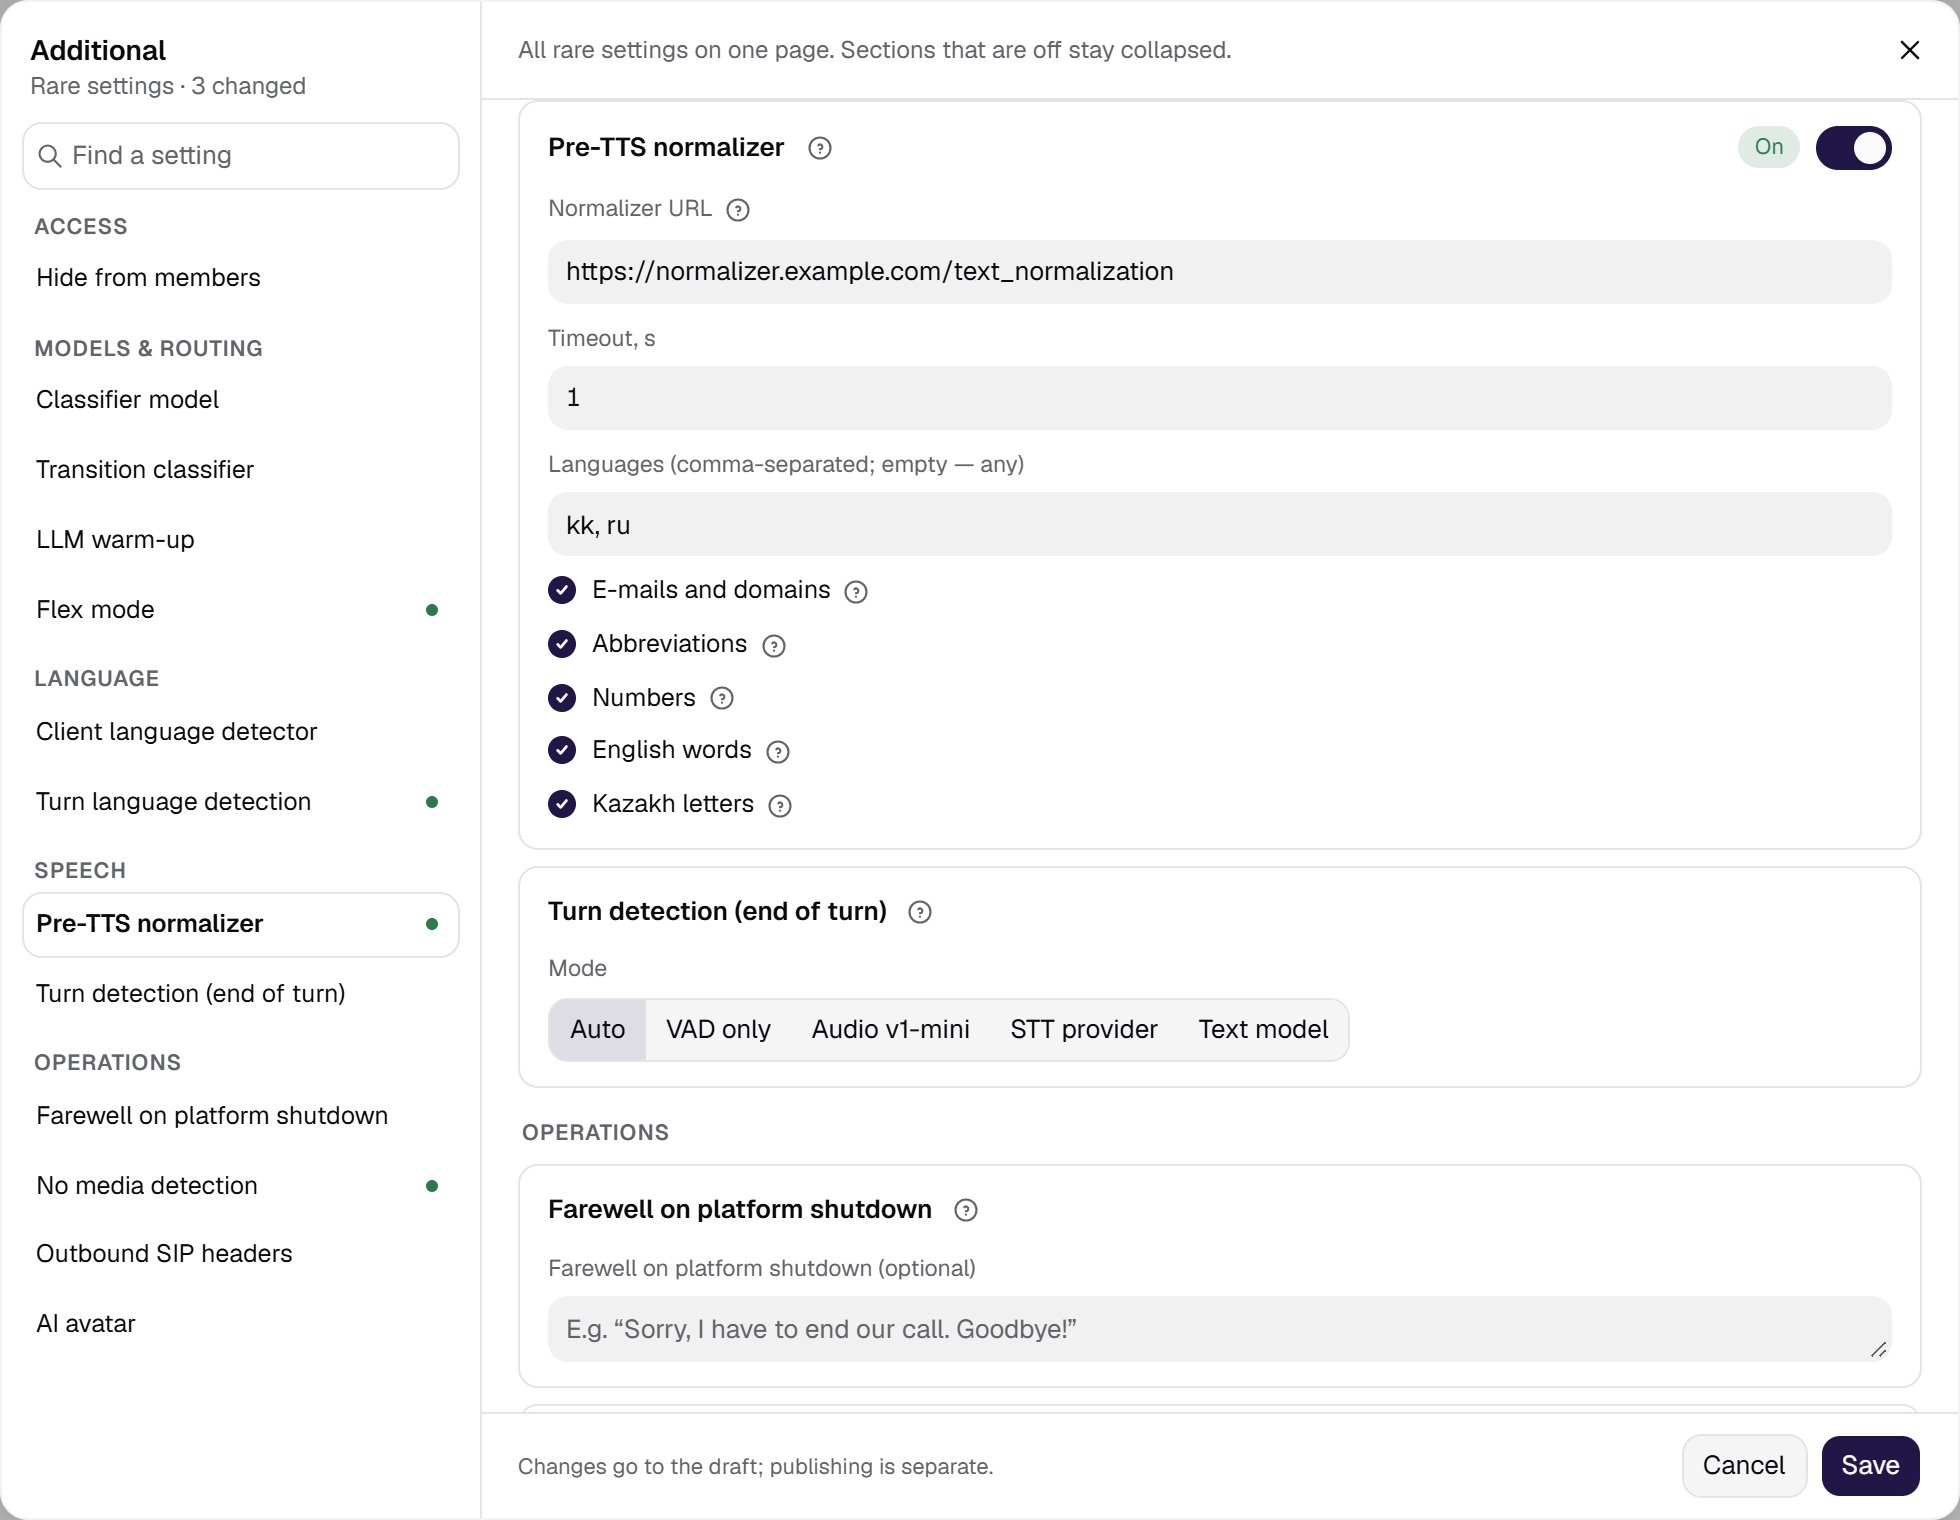
How the end of the caller’s turn is detected. The section is in Additional → Speech → Turn detection (end of turn). The Mode is one of five segments; hover over a segment to see its full name:- Auto — the server default; existing agents keep their behaviour.
- VAD only — end of turn by silence only. Recommended when the language is outside detector support, for example Kazakh.
- Audio v1-mini — a local audio model that listens to intonation, rhythm and timing. Russian and Kazakh are not among its supported languages. It adds unlikely_threshold (scalar) and Per-language thresholds (JSON).
- STT provider — the ASR provider decides. Min endpointing delay is added on top of the provider’s own delay, so the waits add up.
- Text model — the only mode that supports Russian; the model is deprecated. It adds unlikely_threshold (scalar).
Active listening
Active listening is a switch in the Turn-taking group. While the caller speaks at length, the agent utters short acknowledgements such as “uh-huh”. It is not a dialogue turn: the word goes on a separate audio track, never reaches the transcript and does not affect turn detection.- Frequency (0..1) — how often it triggers.
- Words (comma-separated) — empty means the default set in the current call language; a custom list is used as is.
Phrase fixups
The Phrase fixups switch in the Turn-taking group applies the organization’s replacement dictionary to this agent’s replies. See Phrase corrections and pauses.Background audio
An ambient recording — office noise, say — is mixed under the agent’s voice and makes the conversation feel more natural. It loops seamlessly for the length of the call and does not affect recognition: the background is never analyzed as speech, so neither voice detection nor the transcript change because of it.- Background audio — a switch in the Turn-taking group. The fields below appear when it is on.
- Audio asset — pick a recording. The list has two groups:
- Standard — platform backgrounds, the same for every organization: Keyboard and Keyboard, short;
- Uploaded — your organization’s files. Upload audio… (wav/mp3/ogg/opus) adds a new one, and it becomes available to every agent of the organization right away. An uploaded file cannot be deleted from an agent.
- Background volume — how loud it is mixed against the agent’s voice.
Pre-TTS normalizer
Turns email addresses, abbreviations, numbers and Latin script into a speakable form before synthesis. The section is in Additional → Speech → Pre-TTS normalizer.- The switch in the section header turns it on. The address of the normalization service is set by the platform.
- Timeout, s — how long to wait for the normalization service.
- Languages (comma-separated; empty — any) — a language restriction.
- E-mails and domains, Abbreviations, Numbers, English words, Kazakh letters — what to normalize.